A homelab with nothing to rotate, part 2: configuration, conditions and the last key
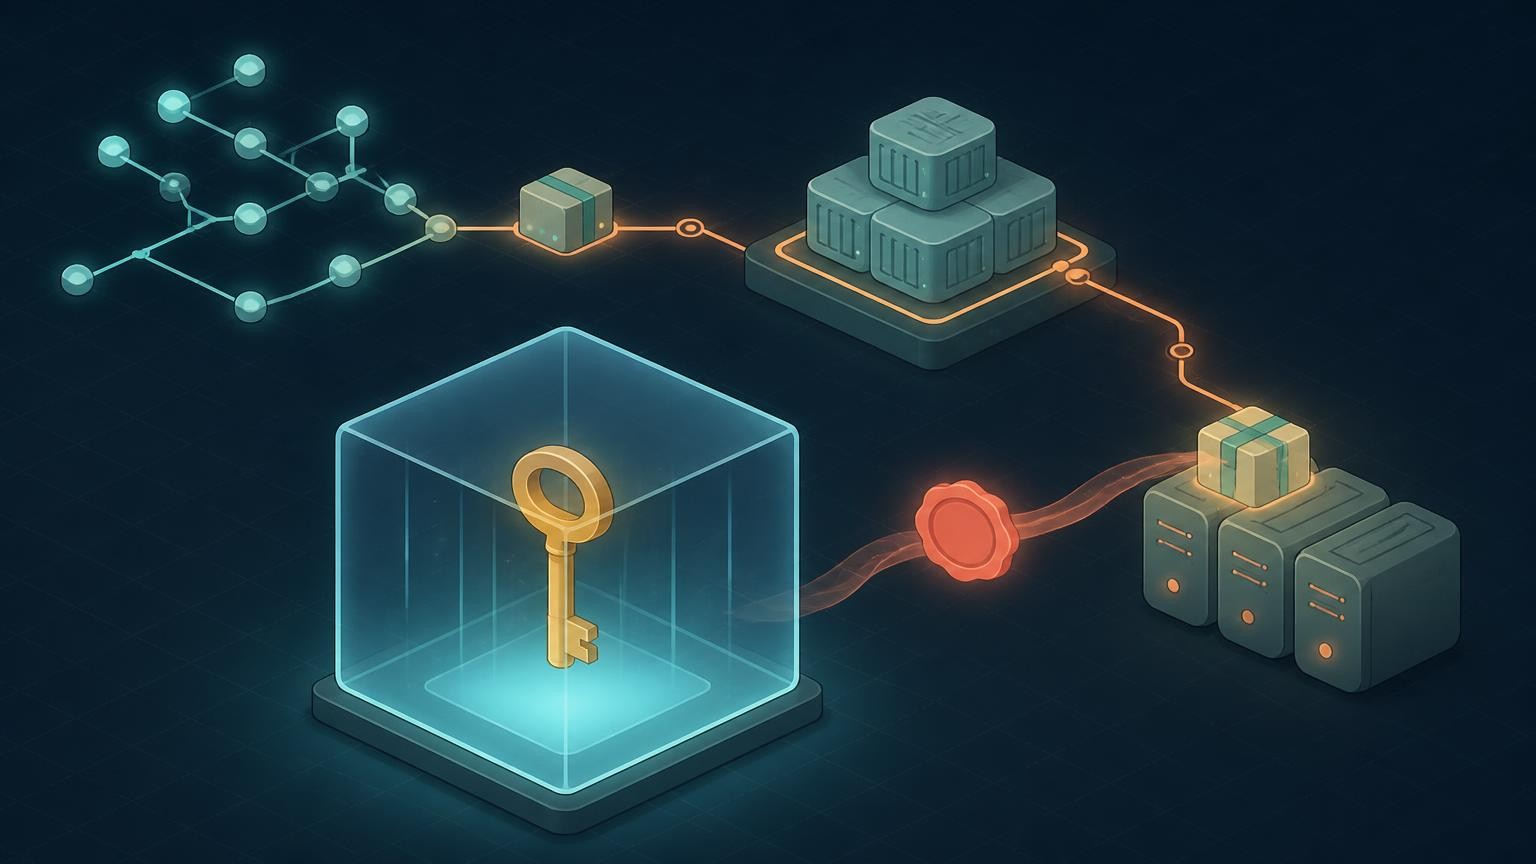
Part one replaced stored keys with badges. A workload, such as a CI run on GitHub or a pod in the cluster, asks whoever runs it for a short-lived signed token that says who it is. A cloud provider has been told which tokens to trust, under which conditions, and trades a matching one for an hour of access. With that, CI pushes images to a cloud registry and the cluster pulls them as the pod that needs them, with nothing stored anywhere.
This part picks up where that left off: with the cluster’s own configuration, which turned out to need a different trick, and then with the parts that decide whether the whole thing is actually secure.
Letting Flux read its configuration without GitHub
Images are half of what a cluster pulls. The other half is its configuration: the manifests that say which applications run, in which version, with which settings. In my cluster that job belongs to Flux, a GitOps tool. It watches a git repository, and whenever something changes there it applies the change to the cluster, so that what runs is always what is written down. Merging a pull request is deploying.
To watch a repository, Flux has to read it, and my repositories are private. So Flux held a key: first an SSH deploy key, later the private key of a GitHub App, which is GitHub’s way of giving a program its own account. Both are stored credentials of exactly the kind these posts are about, and GitHub offers no way around them. It accepts federated tokens from its own Actions runs when they talk to other clouds, but nothing presents a badge to GitHub’s own API and gets in.
The way out is to stop the cluster from reading git at all.
Container registries can hold more than container images. An OCI artifact uses the same format and the same protocol, but carries whatever files you put in it, and Flux can read its configuration from one instead of from git. So on every merge to the main branch, a CI workflow packages the repository into an artifact and pushes it to the registry from the first part, proving who it is with its GitHub token. Flux polls the registry, sees the new artifact, and applies it. It authenticates the same way the image pulls do: as its own ServiceAccount, with a token the cloud has been told to trust.
The publishing side is two commands in a workflow, using Flux’s own command-line tool:
flux push artifact "oci://<registry>/<repo>/manifests:sha-$GITHUB_SHA" \ --path . \ --source "$GITHUB_SERVER_URL/$GITHUB_REPOSITORY" \ --revision "main@sha1:$GITHUB_SHA"flux tag artifact "oci://<registry>/<repo>/manifests:sha-$GITHUB_SHA" --tag mainEach artifact is stored under the commit it came from, and the main tag moves to the newest one. The --source and --revision flags are worth keeping: they record where the files came from, so Flux can still tell you which git commit it applied, even though it never saw git.
The cluster side replaces the git source with an OCI one, pointing at that tag:
apiVersion: source.toolkit.fluxcd.io/v1kind: OCIRepositorymetadata: name: flux-system namespace: flux-systemspec: interval: 1m url: oci://<registry>/<repo>/manifests ref: tag: main provider: <aws | azure | gcp> serviceAccountName: <a ServiceAccount the cloud trusts>Flux does the token exchange itself here; no kubelet plugin is involved. provider says which cloud to talk to, and serviceAccountName says which identity to use, so each source can have its own and none of them has to share the identity of Flux as a whole. At the time of writing, that per-source identity sits behind a feature flag on Flux’s source controller, which has to be switched on.
Moving the source had a side effect I had not planned for, and it removed the second key on my list. Flux can also keep application images up to date: when a new version is published, it writes the new version number into the configuration and commits that to git. That needs write access to the repository, so it needed its own key. It also needed an exemption from branch protection, the rule that nothing reaches the main branch except through a reviewed pull request, because a bot committing straight to main is exactly what that rule forbids. Moving the commit into CI would not have helped: on a personal GitHub account, the token GitHub hands its own CI runs cannot be given that exemption at all. Keeping version updates in git meant keeping a stored credential.
With an artifact in between, it does not have to go through git. For each application, the workflow that builds its artifact looks up the newest image version in the registry and writes it into the files it packages, so the version lives in the artifact and is never committed. Nothing writes to the repository any more, the key that did so is gone, and branch protection stays on without exceptions.
Two things work differently from then on.
Rolling back no longer needs git. Every artifact is still in the registry under its own commit, so going back means moving the main tag to an older one. Flux applies it within a minute. The next merge moves the tag forward again, so a rollback that should stick still needs a revert in git, but in an emergency the tag is quicker.
And checking a deploy needs more care, because a command that succeeds is not proof that the cluster runs what you merged. Telling Flux to reconcile can succeed against the artifact it already has, if CI has not pushed the new one yet. What does prove it is the commit Flux reports having applied, which it knows thanks to --revision above. Wait for the workflow that publishes the artifact to finish, ask Flux to fetch from the source again, and compare that commit with the one you merged. Anything less tells you a command ran.
Who may do what
Everything so far rests on one sentence: the cloud has been told which tokens to trust. That sentence is where this setup is secure or not, and it is the part that is easiest to get wrong when you copy it. A key at least makes its danger obvious. A trust rule that is slightly too broad looks exactly like one that is right, and it works just as well, for you and for whoever else it lets in.
Start with what the badge says. A GitHub Actions token carries a few dozen claims, the statements GitHub signs about the run. Trimmed to the ones that matter for access, it looks like this:
{ "repository_id": "123456789", "repository_owner_id": "987654", "ref": "refs/heads/main", "event_name": "push", "job_workflow_ref": "owner/repo/.github/workflows/publish.yml@refs/heads/main"}Each of these is worth requiring, for a different reason.
repository_idis the repository by number, not by name. Names can be reused: delete a repository, or rename it, and someone can create a new one under the old name. The number belongs to that one repository forever.repository_owner_iddoes the same for the account that owns it.refis the branch or tag the run is for. Requiring the main branch means a run for a pull request, or for a branch someone pushed five minutes ago, gets nothing.event_nameis what started the run. A push to main and a manual run on main are different things, and you may want only one of them.job_workflow_refnames the workflow file that is running, and the branch it was read from. This is the one people leave out, and it matters most for anything that writes. Any workflow in the repository can ask for a token. Without this condition, every workflow on main can push to your registry just as well as the one that was meant to: the one that runs tests, the one somebody adds next year, and any of them that runs a third-party action you have never read.
Every cloud lets you require these, in its own syntax: conditions on a trust policy, a federated credential’s subject, or an expression on the provider. Some only look at a single claim, sub, a string GitHub builds from a few of the others. GitHub lets you change which claims go into that string, and repositories created since mid-2026 include the numeric IDs in it by default. Find out which claims your cloud actually checks before you rely on one.
The cluster side is simpler, and that is a reason to look at it twice. A pod’s token says little more than “ServiceAccount S in namespace N”, so the trust rule can only name those. Anyone who can create a pod in that namespace with that ServiceAccount gets its access, so namespace permissions are part of the trust boundary now. My rule admits a short list of named ServiceAccounts, and nothing else in the cluster can get a token the cloud accepts.
Then a rule that is easy to miss: find out how far a grant reaches. On Google, the trust rules sit in groups called pools, and a permission granted to “repository 123456789” applies to tokens admitted by any rule in that pool, not just the one you were thinking of. When a read-only rule and a write rule share a pool, they quietly share each other’s access. I keep one pool per kind of privilege for that reason, and one registry repository per source of configuration, because the registry grants access per repository: with a shared one, one project’s CI could overwrite another’s manifests. Other clouds draw these lines in different places. The habit that carries over is to keep reading and writing in separate trust rules, and to test from the reading side that it cannot write.
That last part is the same lesson as with the image pulls. A rule that lets the right workflow in proves half of what you need. The other half is a workflow it should refuse, and watching it be refused.
The one key I kept
There is one thing a badge cannot do here: change something on GitHub itself.
I publish a small command-line tool through Homebrew, the package manager many people use on macOS. Homebrew finds packages in a tap, which is just a git repository holding a short description of each package: where to download it, and the checksum it must have. So every release of the tool has to end with a commit to a second repository, the tap. And GitHub does not accept federated tokens for its own API. A workflow can prove who it is to every cloud there is, but to push to another repository it needs one of GitHub’s own credentials: a personal access token, a deploy key, or a GitHub App’s private key. All three are something stored. The only credential that is not, the token GitHub gives each workflow run, works for the repository the run belongs to and nowhere else.
So the key stays. What I could change is where it lives and who can use it.
A GitHub App authenticates by signing a short statement with its private key, which GitHub then trades for an hour of access to the repositories the App is installed on. The signing is the only thing the key is ever used for. That means the key does not have to be anywhere a program can read it. It only has to be somewhere a program can ask for a signature.
Every cloud has a key management service for exactly that: it holds a private key, signs with it on request, and never hands it out. GitHub generates an App’s keys itself and hands you the private half once, as a file. I imported that into the key management service as a key that cannot be exported, and deleted the file. That was the only moment anyone held the key, and from then on it exists in one place, where nobody can read it, me included.
Permission to ask for a signature goes through the same federation as everything else. The release workflow presents its GitHub token, and the trust rule admits it only in the tool’s repository by number, only for a version tag, and only from the release workflow file. The one other way in is a small test workflow that I start by hand on the main branch, to check that signing still works without making a release. That run gets permission to sign, signs, receives an hour of access to the tap, and pushes the update. Everything up to the last step is a badge. It is federation with a key-shaped last step.
There was one more reason to keep it. The tap is protected like any other repository: changes go through a pull request. The App is the single exemption to that rule, and on a personal account it is the only kind of exemption that comes without a readable secret. GitHub will not let its own CI token be exempted there, the same limit as with Flux’s version commits. Keeping the App keeps the pull request rule, and leaves room to require a second reviewer one day.
Rotating it is still possible: have GitHub generate a new key for the App, import it as a new version, switch over, then delete the old one. But nothing forces it any more. A key that cannot be copied cannot leak through a log or a backup, and the reason rotation schedules exist was that kind of leak.
I also designed the alternative, and put it on the shelf. The release could attach the package description to the release itself, with a signed record of which workflow built it. The tap would then fetch new releases on a schedule, verify that record, and commit with its own CI token. No App, no key at all. It only works if that token can be exempted from the pull request rule, though, and that is possible for repositories owned by an organisation, not by a personal account. If the tap ever moves to an organisation, the last key goes.
When the cloud is down
Part one listed the cloud as a dependency. This is what that means in practice, because “the cluster depends on the cloud” sounds worse than it is, and in one place it is worse than it sounds.
If the registry or the token exchange is unreachable, nothing that is already running notices. Pods keep running, and the kubelet only needs the registry to fetch an image it does not have. A pod that restarts on a node that still holds its image starts as before. Credentials the kubelet already has stay valid until they expire, close to an hour, so a short outage passes without a trace. What fails is a pod that needs an image the node has never pulled: a new version, or a pod moved to another node. It waits, retrying, until the registry is back.
Flux keeps working too, but only with what it already has. The controller that applies configuration keeps applying the last artifact it fetched, every few minutes, as it always does. Nothing new arrives, so a merge in that time is not deployed until the registry is reachable again.
That re-applying is also why the obvious fix does not work. If you need to change something during an outage, say a broken setting that has to be reverted now, kubectl apply of the fix lasts until Flux’s next pass, which puts the old artifact back. So the escape hatch has to switch Flux off for that part of the cluster first, apply from a checkout of the repository, and hand control back once the registry is reachable:
flux suspend kustomization <name>flux build kustomization <name> --path ./<its path> > built.yamlkubectl apply --server-side --field-manager=kustomize-controller -f built.yaml# later, once the registry is back:flux resume kustomization <name>flux build matters here. It renders the files from the checkout the way Flux would, with the settings Flux adds on top, such as a target namespace, so what you apply is what Flux would have applied. Applying it under Flux’s own field manager means Flux takes the objects back over cleanly when it resumes, and resuming makes the registry the source of truth again.
One trap is particular to the version trick from earlier. For applications whose image versions live only in the artifact, a checkout from git has old versions in it, and applying it would quietly roll those applications back. The last artifact’s versions are still known inside the cluster, in the status Flux keeps about its source, so my script copies them into the checkout before building. Without that step, the escape hatch is a rollback.
I have rehearsed both halves. The script applied one part of the cluster from a checkout, with Flux suspended, and handed it back without a change. And the controller that fetches artifacts keeps them in temporary storage, so a restart throws them all away and fetches everything again. Restarted on purpose, it had every source back in about five minutes. That rehearsal ran with the cloud reachable, and it shows the one place where an outage is worse than it sounds: if that controller restarts while the registry is down, it starts empty. The cluster keeps running what it has, but Flux has nothing to apply until the registry returns, and the escape hatch above is the only way to change anything.
Rebuilding the cluster from scratch has one step outside it. A new cluster has a new signing key, so the cloud has to be told to trust that key before Flux can fetch anything, the same planned step as replacing the key on the existing cluster. It is written down next to the bootstrap steps. I have run them against the live cluster without applying anything, but not yet on a new one, so that is the part of this I would test before I needed it.
Wrapping up
Back to the list from the start of part one. There were five long-lived keys.
- The token for pulling images is gone. Pods pull as their own ServiceAccount.
- The key Flux used to read its configuration is gone. The configuration comes from the registry.
- The key for writing version updates back is gone. Nothing writes to git any more.
- The key copied into four places so builds could fetch a private library went the same way as the images, though I did not have room to show it. The library is now served from the same cloud’s registry, which can host language packages as well as images, and every build fetches it with its own badge. That includes the bot that keeps dependencies up to date, which accepts a federated identity in its configuration.
- And the key for publishing the package is still there, inside a service that only ever signs with it.
None of them was replaced by another secret, and the thing to rotate is down to one key that can’t be copied.
If you take one thing from these posts for your own setup, let it be the test, not the mechanism. Replace a secret only with something you can check in both directions: it lets the right thing in, and it keeps the wrong thing out. The first check you will do anyway, because otherwise nothing works. The second is the one that tells you the new rule does anything at all. A pull that succeeds might be the identity at work, or a leftover credential, or a cached image. Until you have watched something be refused, you have not removed a credential. You have only stopped seeing it.
If you run your own cluster and pull from Google’s Artifact Registry, the credential provider plugin I wrote for that is at gcp-wif-credential-provider. On Google’s managed Kubernetes you will not need it: Google’s own plugin covers that.
What these posts left alone are the secrets applications hold for themselves: database passwords, API keys for other people’s services. Those are still secrets, and they are a different post.