

The model never writes a number, part 2: harnessing and localising LLM output
Part one was about a daily summary of my investment portfolio, written by a language model and sent to my phone. It read well and was wrong in ways I could not see: a missing value shown to the model as zero, a partial sale described as a crash. Both times, the model gave a sensible answer to a question its data could not answer. The fixes moved the facts into code. Unknown stays unknown, and each holding’s movement is worked out before the prompt is written, so the model describes a result instead of solving a puzzle.
That still left the model one job too many: it typed every number.
Numbers in a style of their own
While that was going on, the dashboard learned to write amounts the way I do: a point between thousands, a comma before the cents. The summary shown right next to it did not. The dashboard said 52.418,37 and the paragraph beside it said 52418.37 EUR.
That was not even one consistent style. The model re-typed every figure it was given, in whatever notation it picked that day. One evening it wrote 52,418.37 EUR and “0.35 percent”. The next it wrote 52201.90 EUR, and a few days later “0.12%”. Dutch notation never came up, because nothing told it which notation I read.
The style was the visible part. The worse part was that some figures were never in the prompt at all. The headline percentage, and each holding’s share of the portfolio, were left to the model to work out, and it worked them out in prose. Twice it described a holding of just under half the portfolio as “more than half”. Nobody checks “more than half” against a calculator. It reads like a fact.
The obvious fix is one more line in the prompt: write numbers the Dutch way. I did not add it, for three reasons.
- The model would still be doing the arithmetic. A wrong share written with the right separators is still wrong.
- The text would be tied to one notation. A summary is written once, stored, and shown again later. Change the setting, and every summary written before the change keeps the old notation.
- Nothing could check it. A test can assert what code returns. It cannot assert which notation a model will choose tomorrow.
This was the sale-as-a-crash problem from part one again, in a smaller form. The model had been given two jobs, choosing the words and handling the numbers, and it was good at only one of them. Part one moved the arithmetic out of the prompt. The next step was to move the numbers out of the reply.
The model writes names, not numbers
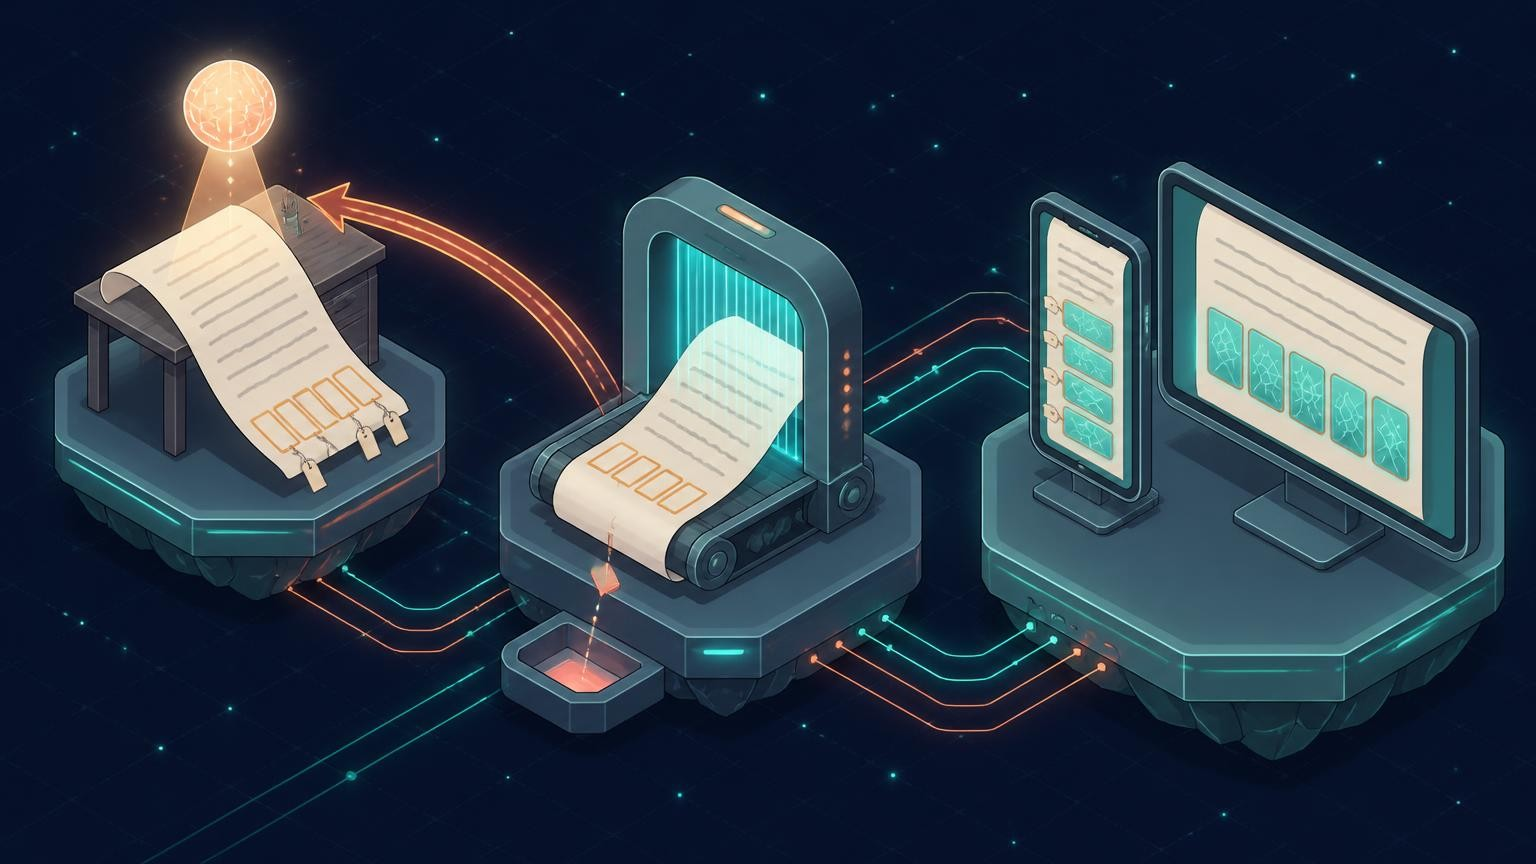
The split I ended up with: code decides what the figures are and how they look, and the model decides only the words around them.
- Code works out every figure the text may state, including the ones the model used to work out itself, such as the headline percentage and each holding’s share. Each figure gets a name.
- The prompt lists those figures by name. The model writes the name in braces,
{total_today}, and never the digits. - The reply is stored as written, placeholders and all, together with the named values. The stored text does not belong to any notation.
- Whatever shows the summary, the dashboard or the notification on my phone, fills the placeholders in when it is shown, in the reader’s notation, with the same formatting code as the rest of the page.
The prompt still shows the model each value, next to its name. It needs them: it cannot choose between “rose” and “fell”, or between “slightly” and “sharply”, without knowing the size of the move. It is told to write the name instead of the value:
Every figure you may state is listed below as a placeholder in braces,followed by its value in parentheses. Write the placeholder exactly asshown, braces included, and never the value.Never write a number yourself: nothing you worked out, such as adifference, a total or a share.
- Total value: {total_today} (52418.37 EUR)- Change: {change} (431.35 EUR), {change_pct} (0.83%)
A reply now looks like “Your portfolio rose by {change} ({change_pct}) to {total_today}”, and I read “rose by 431,35 EUR (0,83%) to 52.418,37 EUR”. With the setting on English, the same stored sentence reads 52,418.37 EUR.
One detail is easy to get wrong: every figure renders without a sign. Render a loss as a negative number and you get “fell by -9,40 EUR”: the model wrote the direction, and the number writes it again. Direction is the job of the prose. So the stored value keeps its sign, because the record should say what happened, and the rendered value is always a magnitude. The prompt says so, because the model can only pick the right verb if it knows the sign will not be there to do it.
The rendering code is small enough to show nearly whole. Trimmed:
type Figure struct {  Kind     Kind    // Money, Percent or Quantity  Value    float64 // keeps its sign; always renders as a magnitude  Currency string}
var placeholder = regexp.MustCompile(`\{([a-z_]+(?::[A-Za-z0-9._-]+)?)\}`)
// Render fills each {name} in the reader's notation. A name with no// figure is left as written: shown is more honest than guessed.func Render(text string, figs map[string]Figure, f Formatter) string {  return placeholder.ReplaceAllStringFunc(text, func(m string) string {    fig, ok := figs[m[1:len(m)-1]]    if !ok {      return m    }    return f.Format(fig.Kind, math.Abs(fig.Value), fig.Currency)  })}
The optional part after a colon names a figure per holding, such as {move:ACME}. Formatter is whatever already formats numbers for the reader in the rest of your app. Using that one, not a second copy, means the prose and the table beside it cannot disagree. In my case that meant moving the formatting out of the web layer, where it was tied to the incoming request, because the phone notification is built without one.
When this fails, you can see it. A name the model made up, or a figure that went missing, shows up in the text as {change}, in braces. That is ugly, but you notice it, which is more than you could say for “more than half”. A value that is not a finite number, the result of dividing by zero for example, is never stored as a figure. It would render as NaN, and a figure that does not exist is what the word “unknown” in the prompt is for. Summaries written before any of this have no figures and render as they were stored.
Storing the text without its notation had a side effect I like. When I change the setting, summaries written before the change switch notation too. I watched one stored summary render as 2,500.00 and then, after a reload, as 2.500,00.
That covers the numbers from my own data. The news explanations quote numbers code cannot know in advance: “crude fell 3.6%”, “a target of 68 dollars”. For those, the model writes a literal: the number inside the placeholder, as {=3.6%} or {=68 USD}. The notation inside the braces is fixed and strict: a dot for decimals, no grouping, then optionally a scale word such as “billion”, then a percent sign or a currency code. That way the value can be read back without guessing whose notation it was written in. It renders per reader like everything else, and keeps the precision of the source: 6% does not become 6.00%.
This still relies on the model following the rule. The prompt says “never write a number”. Nothing so far makes sure it doesn’t.
Trust, but check every reply
So every reply is checked before it is stored. It can break the rule in three ways: a number written as digits, a name in braces that is not on the list, or a literal that does not follow the strict notation.
What counts as “a number written as digits” is deliberately narrow: anything with a decimal point or thousands separator, or any number next to a currency or a percent sign. A plain whole number passes. News headlines are full of digits that are neither mine nor figures, such as “Q2 earnings” or “S&P 500”, and a check that fired on every summary that mentions the news would soon be ignored. The price is that a stray “12” would get through. Placeholders and literals are removed before the scan, so the digits inside {=3.6%} do not count against it.
When a reply breaks the rule, the app asks once more. The retry continues the conversation: the first reply goes back to the model as its own, followed by a message that quotes each violation, such as "27.73 EUR" is a number you wrote yourself, and asks for the whole text again. Quoting the number with its currency makes a clearer instruction than the bare digits would.
What happens next, in outline:
first := generate(prompt)v1 := Validate(first, figs)if len(v1) == 0 { return first, "clean"}second, err := generate(prompt, first, v1) // first reply + violations namedif err != nil { return first, "retry_failed"}v2 := Validate(second, figs)switch {case len(v2) == 0: return second, "retried_clean"case len(v2) > len(v1): return first, "retried_dirty"default: return second, "retried_dirty"}There is no third attempt, and no failing the whole report. If the retry is no better, the app keeps whichever reply breaks the rule less, and sends it. A summary with one stray number in it beats no summary. The outcome is stored with every summary and counted in a metric, so a rule that starts slipping shows up as a trend, not as a surprise in one notification.
What the check proves is narrow, and that is the point: every number I read was computed by code and formatted by code. It does not prove the words are right. “Fell” next to a figure that rose would pass. The prompt and the sign rule from the previous section carry that part.
How often it fires, against the real model: the summary test runs two real days of my own data through it, three times each. All six replies were clean on the first attempt. The news explanations were tested on the four articles with the most numbers in them. Once, the model wrote a literal with a sign in it, {=-2.7%}, which the strict notation rejects; the retry fixed it. After the prompt said explicitly that literals carry no sign, eight replies out of eight were clean on the first attempt.
Those are small samples. They say the rule is easy for the model to keep, not that it always will be. The retry is a seatbelt, not the mechanism. Without it, the failure is the one this series started with: digits in the model’s own style, sent to my phone, unnoticed, because they read fine.
Three smaller lessons
The app also reads the news. When an article mentions one of my holdings, a second prompt decides whether the article is actually about it. If I held Apple, a story about the apple harvest would mention it without being about it. It writes a short reason for each decision, and for the articles it keeps, a sentence on what the news means for my portfolio. Testing that prompt against the real model taught me three more things.
Give a model an example phrase and it will copy it. The field for the reason offered three sample phrasings in brackets. Three of five rejected articles came back with the same sentence, word for word one of the samples: “the matched word is incidental”. The decisions were right. The reasons were useless, and the reason is the one field that has to say something the decision does not: what the article was about instead. The fix removed the samples and asked for the article’s subject, with one example so specific that copying it would be obviously wrong. The reasons came back distinct (“the harvest of the fruit ‘apple’”, “ECB monetary policy and inflation”), with the decisions unchanged. My first draft of that fix quoted the bad phrase as a counter-example, “do not write …”, which handed it over all the same. A test caught it: it asserts that the prompt offers no phrase to copy. It does not assert particular wording, because wording is a judgement call and the absence of the phrase is not.
“Where it matters” is a question you are handing over. The sentence on what the news means was supposed to say how much of my portfolio the holding is, because that is the only number that tells me how much of my money the news is about. The prompt asked for the holding’s details “where they matter”, with the share as an example. Four answers in five used it. The fifth said something like “positive for your holding of 120 shares, worth 4,800 EUR”: true, and nothing I did not already know. If the answer to “does it matter here?” is always yes, do not ask. The next version required the share, exactly as given and not rounded, since “about 8%” is a different claim from 8.3%. Six runs in a row then stated it, each in slightly different words, which is what quoting a figure looks like, as opposed to copying a sentence. Today that share is a placeholder like the rest.
That gap got through for a dull reason. The test against the real model did check for the share, but it reported a missing one as a log line, not a failure. A warning nobody reads is not a check. It is an assertion now.
What the model sees, it uses. One weekend, on my test setup, the only thing that moved was a currency position. That was enough to trigger a summary, which then retold every holding and the cash share, all unchanged, as every summary had. The prompt listed them all, so the model talked about them all. The fix was in the input rather than in the wording. The prompt now lists only holdings that moved: price changed, size changed, opened or closed. The rest are reduced to a count. Cash appears only when the balance changed, and the third paragraph is written only when there is something new to say.
Where the line sits
After all of this, the split is easy to state. Code owns the facts: what is known and what is not, every sum, units and currencies, the notation, and which holdings are worth mentioning at all. The model owns the rest: which facts lead, how much weight each one gets, and the words. That is still most of what makes a summary worth reading, and it is the part a model is good at.
Every fix in both parts was the same move. Find something the model was inferring, work it out in code, and hand it over as a stated fact. Each time, the result became something a test could check.
This works because the numbers in a daily summary are knowable in advance: a fixed set of figures from a fixed set of data. It does not fit a free conversation about numbers nobody worked out beforehand, such as “what if I sold half of this?”. There I would let the model ask rather than answer: give it a tool that does the sum in code and returns a named figure, and keep the same check on the reply. The next feature I plan, setting up alerts by chatting with the app, follows the same idea: the model can change a rule only through a fixed set of actions, and nothing changes until I confirm a preview. That is a plan, not a result. I have not built it yet.
Part three, out on 16 November, is about running these prompts once they are live: versioning prompts, re-judging old output when a prompt changes, testing against the real model, replaying past days, and the morning every call to the model failed while the app reported itself healthy.